
WSO2 Docs MCP Server
Enables AI assistants to semantically search WSO2 documentation across multiple products using retrieval-augmented generation, with support for local or cloud embeddings.
README
WSO2 Docs MCP Server


"This is an unofficial community project. Not affiliated with or endorsed by WSO2."
A production-ready Model Context Protocol (MCP) server that provides AI assistants (Claude Desktop, Claude Code, Cursor, VS Code) with semantic search over WSO2 documentation via Retrieval-Augmented Generation (RAG).
Under the hood, it uses a blazing-fast dual-ingestion engine:
- GitHub Native: Fetches raw Markdown directly from WSO2's public GitHub repositories via the Git Trees API (avoids web-scraping noise and rate limits)
- Web Crawl Fallback: For products without dedicated GitHub docs repos (like the WSO2 Library)
Architecture
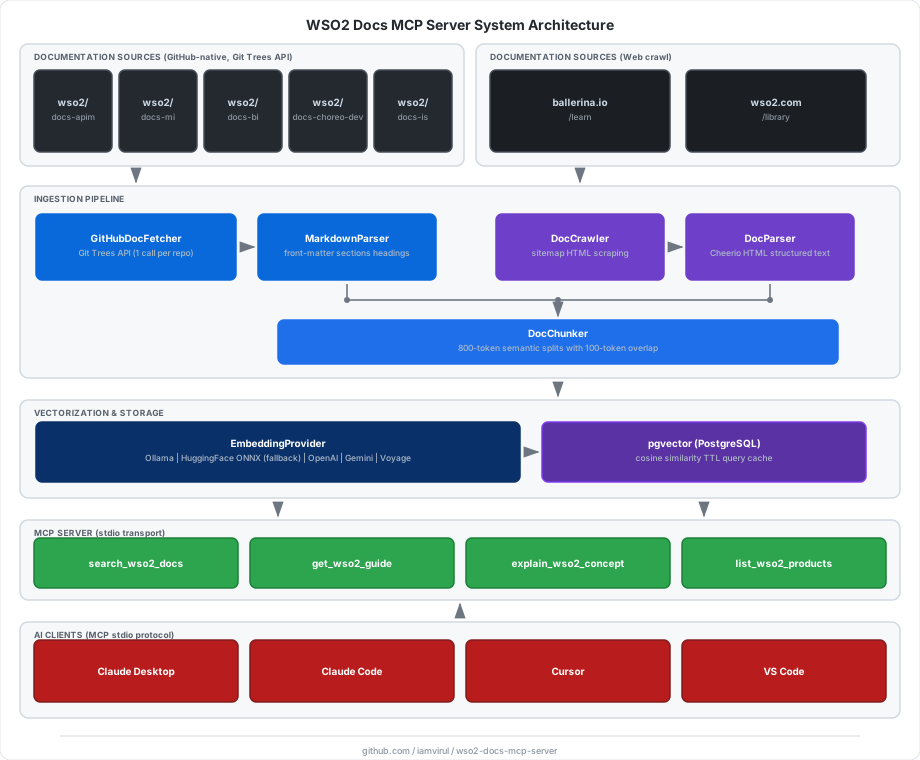
Documentation Sources
| Product | ID | URL |
|---|---|---|
| API Manager | apim |
https://apim.docs.wso2.com |
| Micro Integrator | mi |
https://mi.docs.wso2.com/en/4.4.0 |
| Ballerina Integrator | bi |
https://bi.docs.wso2.com |
| Choreo | choreo |
https://wso2.com/choreo/docs |
| Identity Server | is |
https://is.docs.wso2.com/en/latest |
| Ballerina | ballerina |
https://ballerina.io/learn |
| WSO2 Library | library |
https://wso2.com/library |
Prerequisites
- Node.js ≥ 20
- Docker (for pgvector)
- Embeddings - no API key required by default:
- Ollama (recommended) - runs locally, model auto-downloaded on first run
- If Ollama is not running, the server automatically falls back to HuggingFace ONNX (in-process, also downloads automatically)
- Cloud providers are also supported: OpenAI, Google Gemini, Voyage AI
Quick Start
Choose the setup path that fits your use case:
- Install from npm - simplest, no cloning required
- Clone and build - for development or contributions
Install from npm
Install the package globally to get the wso2-docs-mcp-server, wso2-docs-crawl, and wso2-docs-migrate commands available system-wide:
npm install -g wso2-docs-mcp-server
Prefer no global install? You can use
npx wso2-docs-mcp-server,npx wso2-docs-crawl, andnpx wso2-docs-migratein every step below - just replace the bare command with itsnpxequivalent.
1. Start pgvector
Download the docker-compose.yml and start the database:
curl -O https://raw.githubusercontent.com/iamvirul/wso2-docs-mcp-server/main/docker-compose.yml
docker compose up -d
2. Start Ollama (optional but recommended)
Install Ollama and pull the default embedding model:
ollama pull nomic-embed-text
ollama serve
No Ollama? Skip this step. The server automatically falls back to HuggingFace ONNX - model downloads on first use with no extra setup.
3. Run database migration
DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  wso2-docs-migrate
Run migration again whenever you change
EMBEDDING_DIMENSIONS(i.e. switch embedding provider). The script detects and handles dimension changes automatically.
4. Index WSO2 documentation
# Index all products (first run downloads the embedding model automatically)
DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  wso2-docs-crawl

# Index a single product (faster, great for testing)
DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  wso2-docs-crawl --product ballerina --limit 20

# Force re-index even unchanged pages
DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  wso2-docs-crawl --force
Available product IDs: apim, mi, bi, choreo, is, ballerina, library
5. Configure your AI client
The MCP server is launched on demand by your AI client - no background process needed.
Claude Desktop - edit ~/Library/Application Support/Claude/claude_desktop_config.json:
{
  "mcpServers": {
    "wso2-docs": {
      "command": "wso2-docs-mcp-server",
      "env": {
        "DATABASE_URL": "postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs",
        "EMBEDDING_PROVIDER": "ollama"
      }
    }
  }
}
Claude Code - run once in your terminal:
claude mcp add wso2-docs \
  --transport stdio \
  -e DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  -e EMBEDDING_PROVIDER="ollama" \
  -- wso2-docs-mcp-server

# Verify
claude mcp list
Cursor - create .cursor/mcp.json in your project root:
{
  "mcpServers": {
    "wso2-docs": {
      "command": "wso2-docs-mcp-server",
      "env": {
        "DATABASE_URL": "postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs",
        "EMBEDDING_PROVIDER": "ollama"
      }
    }
  }
}
VS Code - create .vscode/mcp.json:
{
  "servers": {
    "wso2-docs": {
      "type": "stdio",
      "command": "wso2-docs-mcp-server",
      "env": {
        "DATABASE_URL": "postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs",
        "EMBEDDING_PROVIDER": "ollama"
      }
    }
  }
}
Using
npxinstead of global install? Replace"command": "wso2-docs-mcp-server"with"command": "npx"and add"args": ["-y", "wso2-docs-mcp-server"].
Cloud embedding provider? Add the key to
env, e.g."EMBEDDING_PROVIDER": "openai", "OPENAI_API_KEY": "sk-...".
Clone and build
1. Clone and install
git clone https://github.com/iamvirul/wso2-docs-mcp-server.git
cd wso2-docs-mcp-server
npm install
2. Start Ollama (optional but recommended)
Install Ollama and start it:
ollama serve
No Ollama? Skip this step. The server detects Ollama is not running and automatically falls back to HuggingFace ONNX inference - the model downloads on first use with no extra setup.
3. Configure environment
cp .env.example .env
# Defaults work out of the box with Ollama.
# Only edit if using a cloud provider (OpenAI / Gemini / Voyage).
4. Start pgvector
docker compose up -d
# pgAdmin available at http://localhost:5050 (admin@wso2mcp.local / admin)
5. Run database migration
npm run db:migrate
Note: Run migration again whenever you change
EMBEDDING_DIMENSIONS(i.e. switch embedding provider). The script detects and handles dimension changes automatically.
6. Index documentation
# Index all products
# On first run the embedding model is downloaded automatically (Ollama or HuggingFace)
npm run crawl

# Index a single product (faster, great for testing)
npm run crawl -- --product ballerina --limit 20

# Force re-index even unchanged pages
npm run crawl -- --force
7. Build and start the MCP server
npm run build
npm start
For development (no build step):
npm run dev
8. Configure your AI client
Replace
/ABSOLUTE/PATH/TO/wso2-docs-mcp-serverwith your actual clone path.
Claude Desktop - edit ~/Library/Application Support/Claude/claude_desktop_config.json:
{
  "mcpServers": {
    "wso2-docs": {
      "command": "node",
      "args": ["/ABSOLUTE/PATH/TO/wso2-docs-mcp-server/dist/src/index.js"],
      "env": {
        "DATABASE_URL": "postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs",
        "EMBEDDING_PROVIDER": "ollama"
      }
    }
  }
}
Claude Code:
claude mcp add wso2-docs \
  --transport stdio \
  -e DATABASE_URL="postgresql://wso2mcp:wso2mcp@localhost:5432/wso2docs" \
  -e EMBEDDING_PROVIDER="ollama" \
  -- node "/ABSOLUTE/PATH/TO/wso2-docs-mcp-server/dist/src/index.js"

# Verify
claude mcp list
See config-examples/claude_code.sh for a convenience script.
Cursor - create .cursor/mcp.json - see config-examples/cursor_mcp.json.
VS Code - create .vscode/mcp.json - see config-examples/vscode_mcp.json.
MCP Tools
| Tool | Description |
|---|---|
search_wso2_docs |
Semantic search across all products. Optional product and limit filters. |
get_wso2_guide |
Search within a specific product (apim, mi, bi, choreo, is, ballerina, library). |
explain_wso2_concept |
Broad concept search across all products, returns 8 top results. |
list_wso2_products |
Returns all supported products with IDs and base URLs. |
Example response
[
  {
    "title": "Deploying WSO2 API Manager",
    "snippet": "WSO2 API Manager can be deployed in various topologies…",
    "source_url": "https://apim.docs.wso2.com/en/latest/install-and-setup/...",
    "product": "apim",
    "section": "Deployment Patterns",
    "score": 0.8712
  }
]
Local Embeddings
The default EMBEDDING_PROVIDER=ollama runs entirely on your machine with no API key. The startup sequence is:
Is Ollama running?
├── Yes → Is model present?
│         ├── Yes → Ready (instant)
│         └── No  → Pull via Ollama (streamed, runs once)
└── No  → Download ONNX model from HuggingFace Hub (~250 MB, cached after first run)
           and run inference in-process via @huggingface/transformers
Both paths use nomic-embed-text / Xenova/nomic-embed-text-v1 by default and produce identical 768-dim vectors, so you can switch between them without re-indexing.
Hardware acceleration (HuggingFace ONNX fallback)
When Ollama is not available, the server auto-detects the best compute backend:
| Machine | Detection | ONNX dtype | Batch size | Throughput |
|---|---|---|---|---|
| Apple Silicon (M1/M2/M3/M4) | process.arch === 'arm64' |
q8 INT8 |
32 | ~9 ms/chunk |
| NVIDIA GPU | nvidia-smi probe |
fp32 |
64 | GPU-dependent |
| All others | fallback | q8 INT8 |
16 | ~10 ms/chunk |
Why q8 on Apple Silicon instead of CoreML/Metal?
CoreML compiles Metal shaders on first use (~20 min cold-start). For the typical chunk sizes produced by this server (6–20 chunks per page), the CPU↔GPU transfer overhead eliminates any inference gain. INT8 quantized inference on ARM NEON SIMD is consistently ~100× faster than fp32 CPU with zero cold-start cost.
Benchmark (Apple M-chip, Xenova/nomic-embed-text-v1):
fp32 CPU (before): ~1,000 ms/chunk   (68 chunks ≈ 68 s of embedding)
q8  ARM NEON:          ~9 ms/chunk   (68 chunks ≈  0.6 s of embedding)  ← ~100× speedup
Note: For small crawls (≤ 10 pages) total wall-clock time is dominated by network I/O (HTTPS fetches to docs sites), so the end-to-end improvement is modest. The embedding speedup becomes significant at scale - crawling 500+ pages where embedding previously accounted for hours of runtime. For best crawl performance, run Ollama (
ollama serve) which parallelises inference natively and has no per-chunk overhead.
Environment Variables
Core
| Variable | Default | Description |
|---|---|---|
DATABASE_URL |
- | PostgreSQL connection string (required) |
EMBEDDING_PROVIDER |
ollama |
ollama | openai | gemini | voyage |
EMBEDDING_DIMENSIONS |
768 |
Must match model output dimensions |
CRAWL_CONCURRENCY |
5 |
Concurrent HTTP requests during crawl |
CHUNK_SIZE |
800 |
Approximate tokens per chunk |
CHUNK_OVERLAP |
100 |
Overlap tokens between chunks |
CACHE_TTL_SECONDS |
3600 |
In-memory query cache TTL |
TOP_K_RESULTS |
10 |
Default search result count |
Ollama (default)
| Variable | Default | Description |
|---|---|---|
OLLAMA_BASE_URL |
http://localhost:11434 |
Ollama server URL |
OLLAMA_EMBEDDING_MODEL |
nomic-embed-text |
Model pulled and used via Ollama |
HUGGINGFACE_EMBEDDING_MODEL |
Xenova/nomic-embed-text-v1 |
ONNX fallback when Ollama is not running |
Cloud providers
| Variable | Default | Description |
|---|---|---|
OPENAI_API_KEY |
- | Required if EMBEDDING_PROVIDER=openai |
OPENAI_EMBEDDING_MODEL |
text-embedding-3-small |
OpenAI model |
GEMINI_API_KEY |
- | Required if EMBEDDING_PROVIDER=gemini |
GEMINI_EMBEDDING_MODEL |
text-embedding-004 |
Gemini model |
VOYAGE_API_KEY |
- | Required if EMBEDDING_PROVIDER=voyage |
VOYAGE_EMBEDDING_MODEL |
voyage-3 |
Voyage model |
Embedding dimension reference
| Provider | Model | Dimensions |
|---|---|---|
| Ollama / HuggingFace | nomic-embed-text / Xenova/nomic-embed-text-v1 |
768 (default) |
| Ollama / HuggingFace | mxbai-embed-large / Xenova/mxbai-embed-large-v1 |
1024 |
| Ollama / HuggingFace | all-minilm / Xenova/all-MiniLM-L6-v2 |
384 |
| OpenAI | text-embedding-3-small |
1536 |
| OpenAI | text-embedding-3-large |
3072 |
| Gemini | text-embedding-004 |
768 |
| Voyage | voyage-3 |
1024 |
| Voyage | voyage-3-lite |
512 |
Scheduled Re-indexing
# Run a one-off re-index (checks hashes, skips unchanged pages)
npm run reindex

# Or from the project directory using node-cron (runs daily at 2 AM)
DATABASE_URL=... node -e "
  const { ReindexJob } = require('./dist/jobs/reindexDocs');
  const job = new ReindexJob();
  job.initialize().then(() => job.scheduleDaily());
"
Project Structure
src/
  config/          env.ts · constants.ts
  vectorstore/     pgvector.ts · schema.sql
  ingestion/       crawler.ts · parser.ts · githubFetcher.ts · markdownParser.ts · chunker.ts · embedder.ts
  server/          mcpServer.ts · toolRegistry.ts
  jobs/            reindexDocs.ts
  index.ts
scripts/
  crawl.ts         CLI ingestion pipeline
  migrate.ts       Dynamic schema migration
config-examples/   claude_desktop.json · claude_code.sh · cursor_mcp.json · vscode_mcp.json
docker-compose.yml
.env.example
Development
# Type-check
npx tsc --noEmit

# Run crawl with tsx (no build needed)
npm run crawl -- --product ballerina --limit 5

# Run server in dev mode
npm run dev
Recommended Servers

playwright-mcp
A Model Context Protocol server that enables LLMs to interact with web pages through structured accessibility snapshots without requiring vision models or screenshots.

Magic Component Platform (MCP)
An AI-powered tool that generates modern UI components from natural language descriptions, integrating with popular IDEs to streamline UI development workflow.

Audiense Insights MCP Server
Enables interaction with Audiense Insights accounts via the Model Context Protocol, facilitating the extraction and analysis of marketing insights and audience data including demographics, behavior, and influencer engagement.

VeyraX MCP
Single MCP tool to connect all your favorite tools: Gmail, Calendar and 40 more.

graphlit-mcp-server
The Model Context Protocol (MCP) Server enables integration between MCP clients and the Graphlit service. Ingest anything from Slack to Gmail to podcast feeds, in addition to web crawling, into a Graphlit project - and then retrieve relevant contents from the MCP client.

Kagi MCP Server
An MCP server that integrates Kagi search capabilities with Claude AI, enabling Claude to perform real-time web searches when answering questions that require up-to-date information.

E2B
Using MCP to run code via e2b.

Neon Database
MCP server for interacting with Neon Management API and databases

Exa Search
A Model Context Protocol (MCP) server lets AI assistants like Claude use the Exa AI Search API for web searches. This setup allows AI models to get real-time web information in a safe and controlled way.

Qdrant Server
This repository is an example of how to create a MCP server for Qdrant, a vector search engine.