
mcpgrade
Grades MCP servers on agent usability (A–F) — description quality, schema design, tool naming and token cost, the properties that decide whether a model picks the right tool. Benchmarked across 36 popular servers; a third scored D or F.
README
mcpgrade
Lighthouse for MCP servers. Your server can be 100% spec-compliant and still fail agents — vague descriptions, token-bloated schemas, confusable tool names. mcpgrade scores what compliance checkers can't: whether an LLM can actually use your tools.
npx mcpgrade https://your-server.example.com/mcp   # streamable HTTP
npx mcpgrade --stdio "node ./my-server.js"          # local stdio server
npx mcpgrade --snapshot tools.json                  # saved tools/list output

npx mcpgrade https://mcp-us.example.com/mcp/streamable \
  --header "Authorization: Bearer $TOKEN"           # authenticated remote server
Zero config. No API key. Report in seconds.
What it checks
| Category | Weight | Examples |
|---|---|---|
| Descriptions | 30% | missing/too-short descriptions, undocumented params, placeholder text, duplicate descriptions |
| Schema design | 30% | missing types, no required array, additionalProperties: true, prose-instead-of-enum, deep nesting |
| Naming | 15% | confusable names (get_user vs get_users), generic verbs (process), mixed conventions |
| Token cost | 15% | catalog total budget, per-tool budget — agents pay your schema on every request |
| Consistency | 10% | catalog-wide uniformity; with --probe, live checks that error messages help the model self-correct |
Every finding comes with a concrete fix. Scores are density-normalized: 3 broken tools out of 3 is an F; 3 out of 30 is a dent.
Example
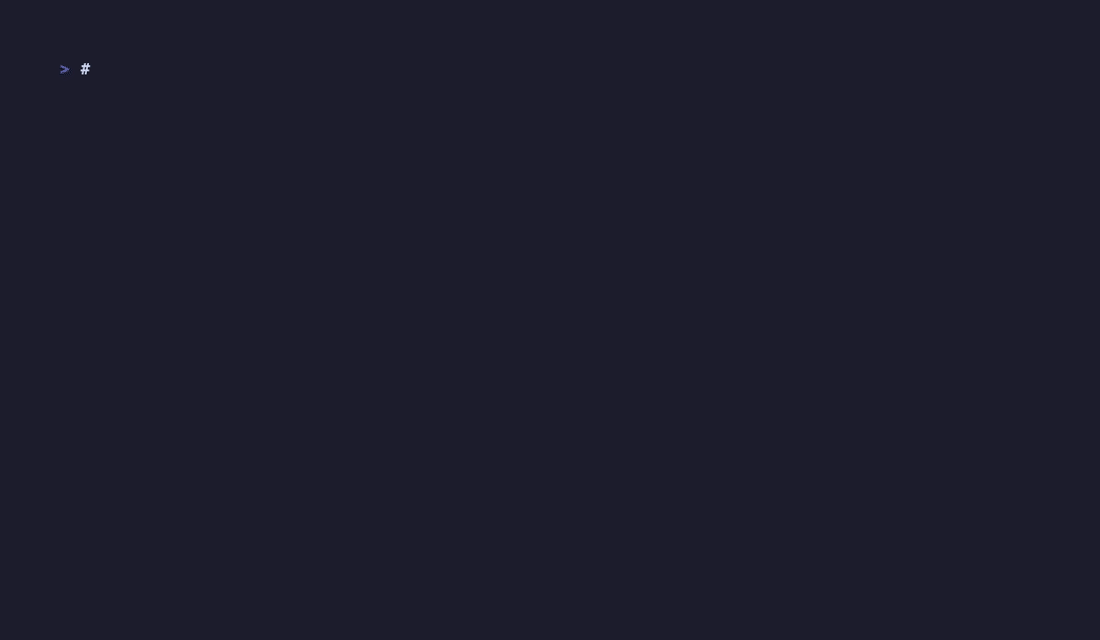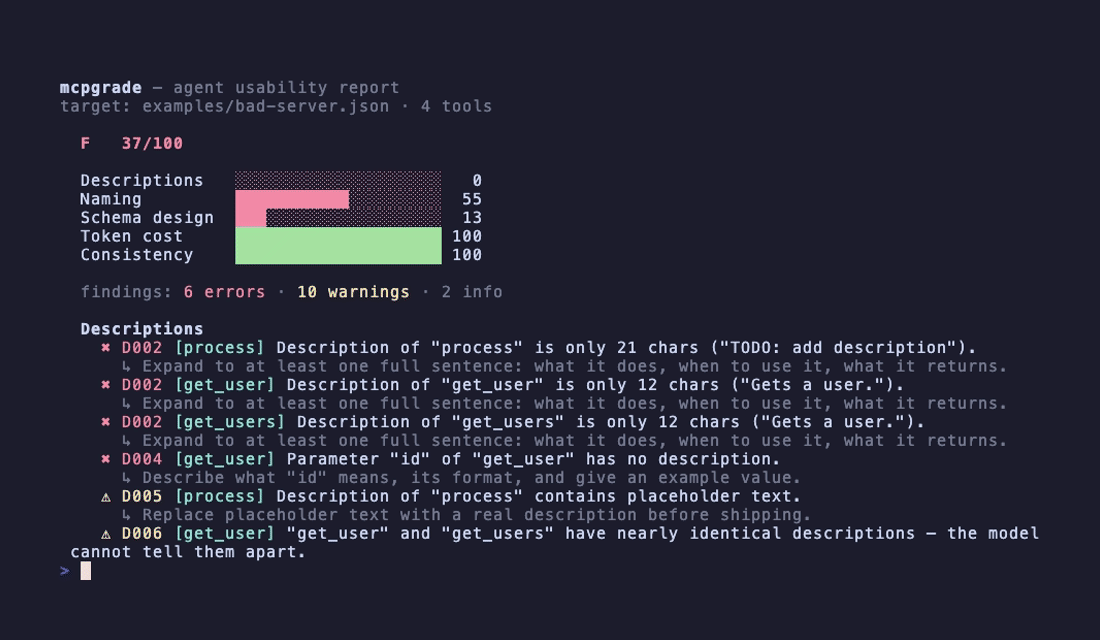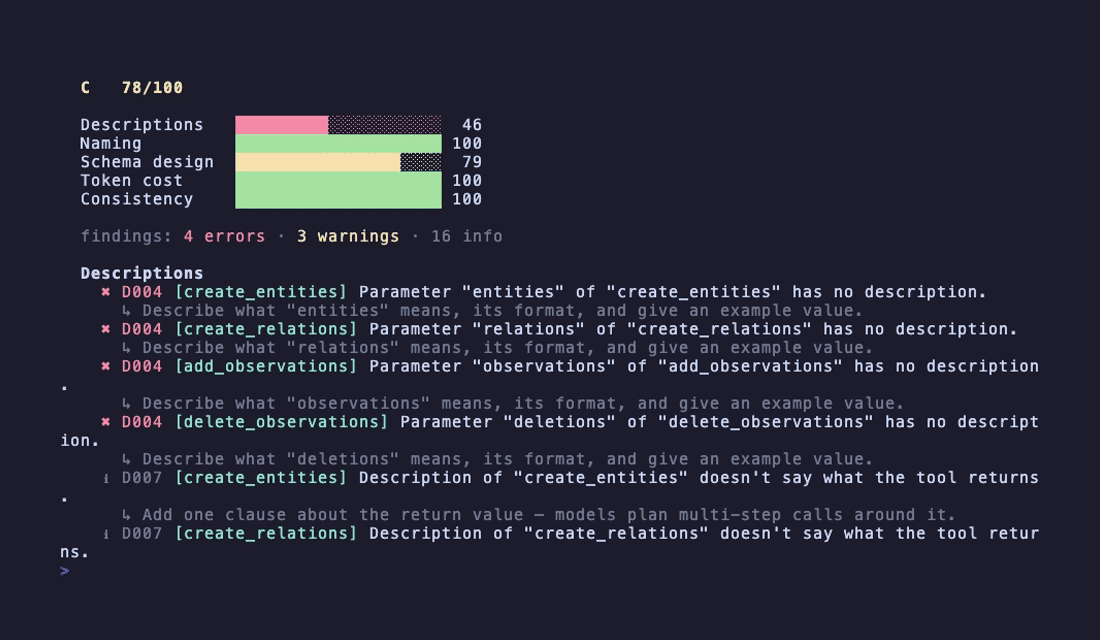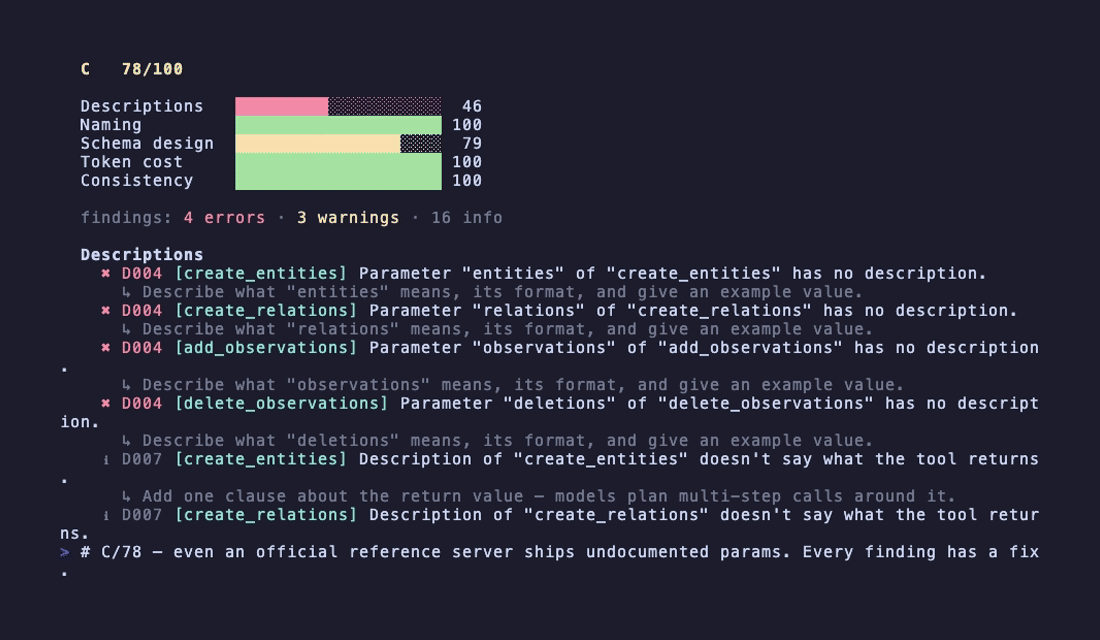
mcpgrade — agent usability report
target: examples/bad-server.json · 4 tools

  F   37/100

  Descriptions   ░░░░░░░░░░░░░░░░░░░░   0
  Naming         ███████████░░░░░░░░░  55
  Schema design  ███░░░░░░░░░░░░░░░░░  13
  Token cost     ████████████████████ 100
  Consistency    ████████████████████ 100

  findings: 6 errors · 10 warnings · 2 info

  Descriptions
    ✖ D002 [get_user] Description of "get_user" is only 12 chars ("Gets a user.").
      ↳ Expand to at least one full sentence: what it does, when to use it, what it returns.
    ...
MCP server mode
mcpgrade also runs as an MCP server, so an agent can grade other servers on your behalf:
claude mcp add mcpgrade -- npx -y mcpgrade serve
Or add it manually:
{
  "mcpServers": {
    "mcpgrade": { "command": "npx", "args": ["-y", "mcpgrade", "serve"] }
  }
}
Three tools, deliberately: grade_mcp_server, explain_rule, list_grading_rules.
Security. In serve mode the target string is chosen by a model, so local launch
commands are restricted to an allowlist (npx, node, python, python3, uv,
uvx, deno, bun, docker). URLs and .json snapshots are always allowed. The
CLI has no such restriction.
Dogfooding. The serve catalog is graded by mcpgrade in CI and must score an A with zero errors (test/serve.test.ts) — if a change drops the grade, the fix is the catalog, not the threshold. Current self-score:
A 96/100 3 tools · 0 errors · 1 warning
The one warning is a rule I disagree with on this catalog: S005 flags target
for describing a fixed value set in prose without an enum. The prose lists
permitted command prefixes for an otherwise free-form string, so an enum is not
expressible. Left in place rather than suppressed — the ruleset is opinionated by
design, and disagreements belong in the open (#10).
Authenticated remote servers
Most hosted MCP servers require a bearer token. Pass headers with --header
(repeatable), or set MCPGRADE_HEADERS="Authorization: Bearer …; X-Tenant: acme":
npx mcpgrade https://your-host/mcp --header "Authorization: Bearer $TOKEN"
Streamable HTTP is tried first, with an automatic SSE fallback for servers on the
older transport. mcpgrade only calls tools/list — it never invokes a tool unless
you pass --probe.
Header values are treated as secrets: they go to the transport and nowhere
else — not the report, not --json output, not the eval envFingerprint. MCP
serve mode accepts no headers at all, since there the target is chosen by a model
and a model has no business handing out credentials.
CI
mcpgrade <target> --json                # machine-readable
mcpgrade <target> --fail-on error       # exit 1 on errors — gate your PRs
mcpgrade <target> --disable S008,N001   # tune rules
mcpgrade rules                          # list all rules
Why
I integrate first-party and third-party MCP connectors into a production AI agent for a living. Most MCP servers fail agents in the same ten ways — none of which show up in a spec compliance check. So I wrote the linter I wished server authors had run before shipping.
mcpgrade vs mcp-lint
Different tools, different questions. mcp-lint checks whether your tool schemas parse correctly across clients (Claude, Cursor, OpenAI strict mode, ...) — syntax-level compatibility. mcpgrade measures whether a model can actually use your tools — description quality, naming confusion, token economics, and live LLM tool-selection accuracy. A server can pass mcp-lint cleanly and still score an F here, and vice versa. They compose well: lint for compatibility, grade for usability. Full side-by-side with concrete outputs: docs/comparison.md.
Roadmap
- [x] v0.1 — static lint engine, 24 rules, A–F scoring
- [x] v0.2 —
--eval: LLM-powered live testing — synthetic task generation, blind tool selection, argument validation, refusal accuracy, confusion pairs. Calibrated on real servers (methodology); costs ~$0.05–0.2 per server on Haiku. Bring your ownANTHROPIC_API_KEY, or any OpenAI-compatible endpoint via--eval-base-url(DeepSeek, OpenRouter, ...);--eval-mockruns offline. RespectsHTTPS_PROXY. - [x] v0.3 —
mcpgrade serve: runs as an MCP server so an agent can grade other servers (allowlisted launchers; the catalog is graded by mcpgrade in CI and must hold an A). PlusenvFingerprinton every eval result — catalog hash, model, temperature, prompt version, task policy — so two scores are comparably or visibly incomparable. - [x] Also shipped: GitHub Action for CI gating, and a public leaderboard of 36 popular servers.
- [ ] v0.4 — the failure taxonomy work, driven by reader feedback: four-outcome scoring, held-out task authoring, silent-vs-observable failures, cross-server collisions, multi-hop evaluation, rule-entailment dedup. Dynamic badges when the scoring model settles.
License
MIT
Recommended Servers

playwright-mcp
A Model Context Protocol server that enables LLMs to interact with web pages through structured accessibility snapshots without requiring vision models or screenshots.

Magic Component Platform (MCP)
An AI-powered tool that generates modern UI components from natural language descriptions, integrating with popular IDEs to streamline UI development workflow.

Audiense Insights MCP Server
Enables interaction with Audiense Insights accounts via the Model Context Protocol, facilitating the extraction and analysis of marketing insights and audience data including demographics, behavior, and influencer engagement.

VeyraX MCP
Single MCP tool to connect all your favorite tools: Gmail, Calendar and 40 more.

graphlit-mcp-server
The Model Context Protocol (MCP) Server enables integration between MCP clients and the Graphlit service. Ingest anything from Slack to Gmail to podcast feeds, in addition to web crawling, into a Graphlit project - and then retrieve relevant contents from the MCP client.

Kagi MCP Server
An MCP server that integrates Kagi search capabilities with Claude AI, enabling Claude to perform real-time web searches when answering questions that require up-to-date information.

E2B
Using MCP to run code via e2b.

Neon Database
MCP server for interacting with Neon Management API and databases

Exa Search
A Model Context Protocol (MCP) server lets AI assistants like Claude use the Exa AI Search API for web searches. This setup allows AI models to get real-time web information in a safe and controlled way.

Qdrant Server
This repository is an example of how to create a MCP server for Qdrant, a vector search engine.